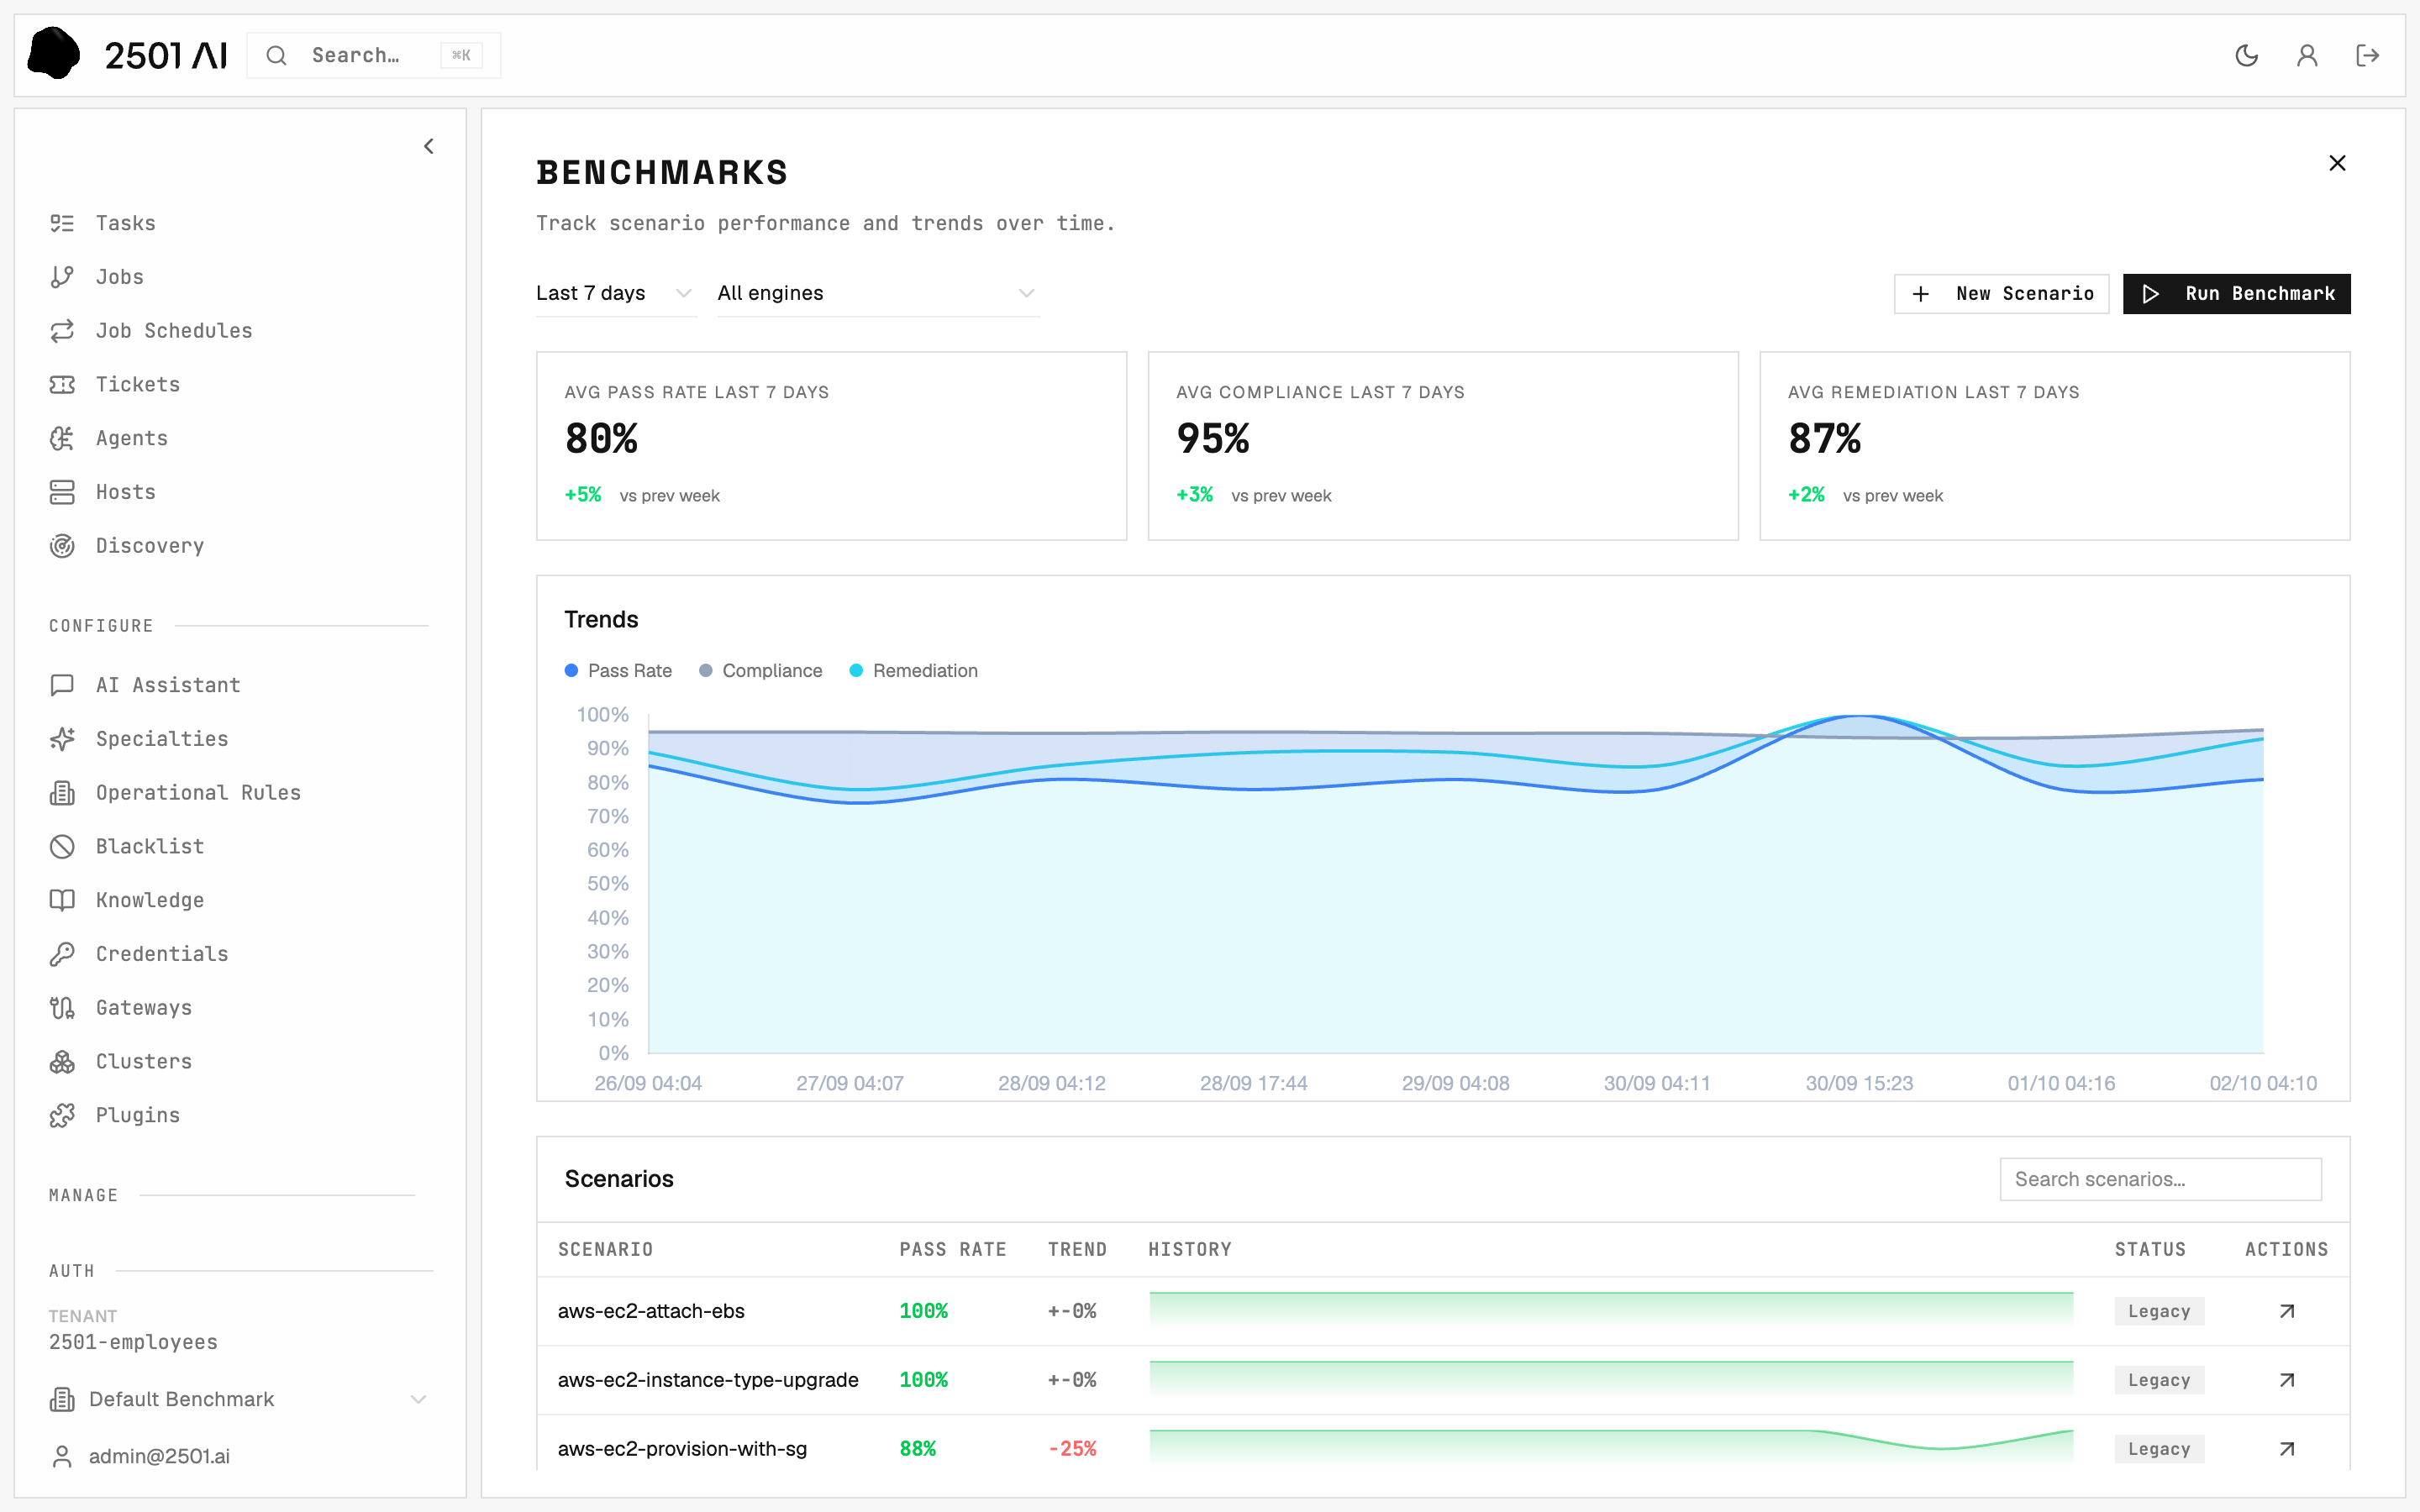
Benchmarks: every scenario's pass rate and trend over time.
Why benchmark
Validate new ticket typologies
Before letting a new specialty handle real tickets, replicate the failure mode on a test host and see how the agent handles it across many runs.
Catch regressions
A previously-passing scenario starts failing after a specialty edit. Trend lines surface it immediately.
Compare models or prompts
Same scenario, a different main engine picked at launch. Same scenario, a different specialty. The scores tell you which behaves better, not just which is faster.
Prove compliance to your team
Auditors get a record: which commands the agent ran, which operational rules it was given, which validation rules passed.
How a run is graded
When the agent is done, the engine checks the scenario’s validation rules. A built-in rule, Job completed, is always checked first. Your rules can match the agent’s commands, messages, and plans, count its tasks, accept a resolution status, or run a shell command on the host and expect an exit code. Each scenario run reports three results:
Verdict and remediation answer different questions: an agent can resolve its job as
success while breaking one of your rules, or follow every rule and still report a partial resolution. Use host_state rules to check the host itself rather than taking the agent’s word for it.
How a scenario runs
Prerequisites
- An agent on each test host. Setup,
host_statechecks, and restore reuse the agent’s connection - its SSH/WinRM credentials, shell, environment, and user. Writesudoortimeoutinto the command itself. - Hosts you can afford to break. Setup commands change the host for real.
- A working model configuration. The models are frozen when the benchmark launches, so a run is graded on the engines you picked.
The CLI runner (legacy)
Earlier versions ran scenarios from files in a repository with the2501 runner CLI and Ansible playbooks, on pre-provisioned hosts or on Lima/Incus VMs. The runner still works, and its runs still show in Command Center, marked Legacy. Its scenarios are not editable in Command Center. See the CLI runner quickstart if you maintain such scenarios.
What to read next
Benchmark in Command Center
Create a scenario, test its setup and restore, run it, and read the result.
Validation rules
Every validator and what it can inspect.