Any user can view providers available to their organization. Tenant-level admins can add, edit, or delete providers in either scope. Organization admins can manage providers in their assigned organizations, but tenant-wide providers are read-only for them. See Users & Organizations.
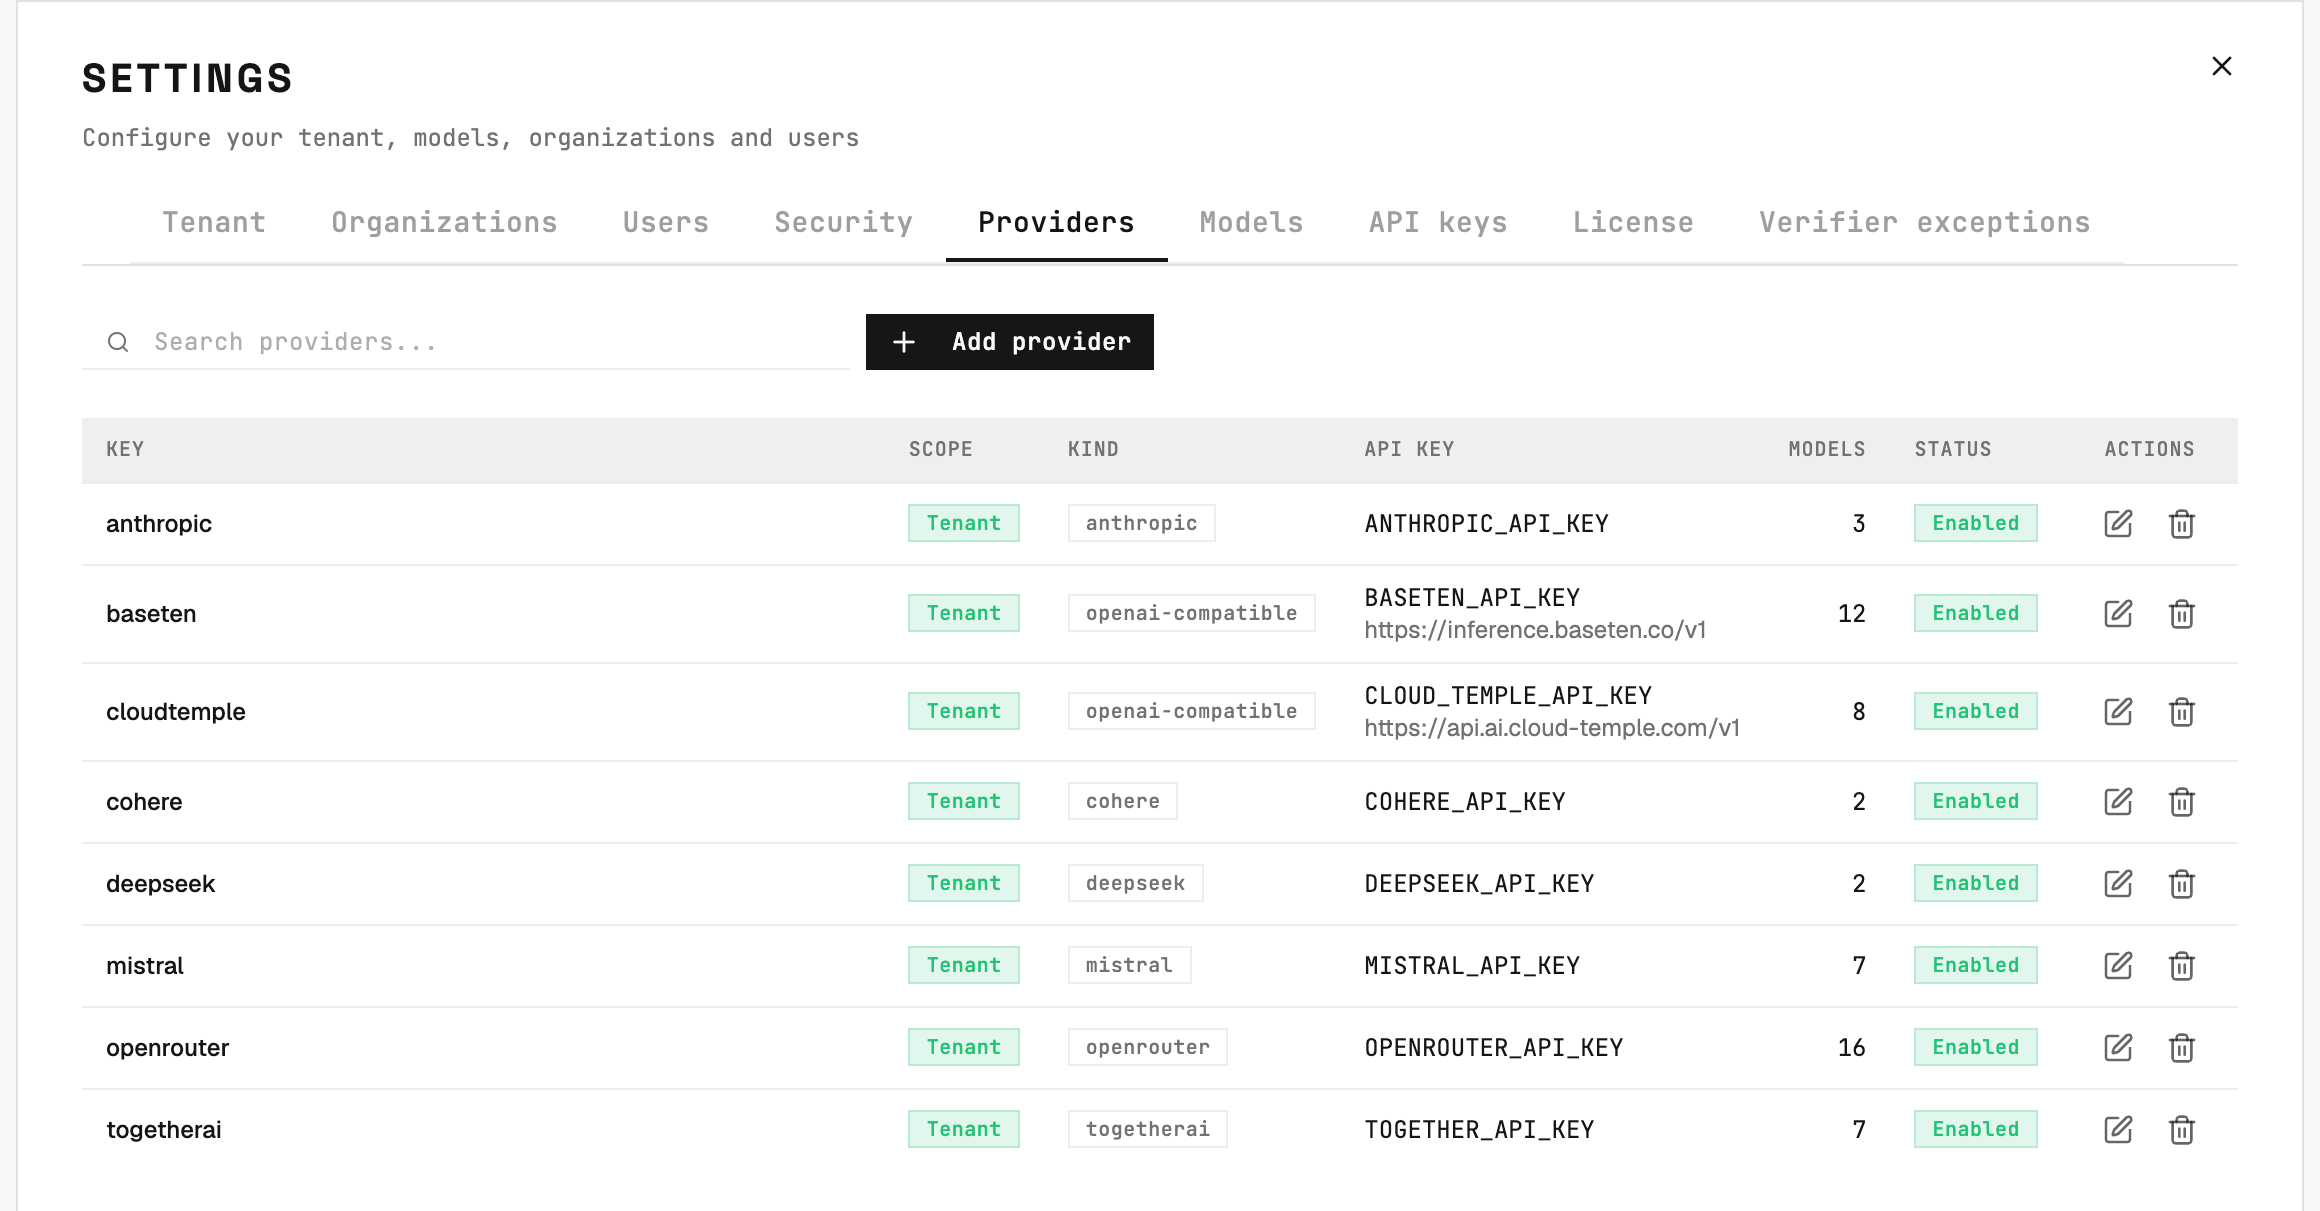
Settings → Providers: each row is an endpoint the engine can call.
Fields
Provider types
Use a compatible type to register a self-hosted model server (vLLM, Ollama, LM Studio) or any vendor exposing an OpenAI- or Anthropic-style API.
Adding a new endpoint of an existing type is pure configuration. Adding a brand-new type (a vendor with its own API shape) requires a 2501 release - contact your Account Executive.
API key resolution
A provider reads its API key from the Credential attached to it. Clicking API key opens a searchable list of credentials available in the provider’s scope. Choosing Scoped to Tenant narrows the list to tenant-scoped credentials. Select a result, or type a listed credential’s full name and press Enter; surrounding spaces are ignored. If credential search fails, use Retry - your saved selection stays unchanged. Rotating a key is editing that credential. Nothing on the engine changes, and the dialog checks the credential resolves before it saves.Providers created before credentials were attachable resolve their key by name instead: a credential of that name first, then - for the built-in provider keys only (
ANTHROPIC_API_KEY, OPENAI_API_KEY, OPENROUTER_API_KEY, MISTRAL_API_KEY, DEEPSEEK_API_KEY, COHERE_API_KEY, TOGETHER_API_KEY, CLOUD_TEMPLE_API_KEY, BASETEN_API_KEY) - an environment variable of that name on the engine. Any other name resolves through a credential or not at all. Re-pick the key in the dialog to attach it directly - the name reference and the environment variable fallback are going away.Providers that do not need a key (e.g. a self-hosted model on a private network) can turn off Requires auth.
Concurrency limit
Max concurrent requests caps how many requests the engine sends to a provider at the same time, across all of its models. Set it when the provider slows down or answers429 under load - for example a self-hosted LLM gateway whose models all share one GPU. A new or existing provider has no limit until you set one.
Requests above the limit wait in line on the engine instead of reaching the provider:
- Tasks go first. Other requests - AI Assistant chats, job planning, model performance tests - wait behind task requests. A request that first arrived 60 seconds ago or more is served in arrival order with the task requests. For a retry, the 60 seconds count from its first try. So a busy job cannot hold back the planning of a new ticket.
- A try is bounded. Each try has 7 minutes in total, for the wait in line and the answer. A try that runs out of time fails like any request that times out. When the engine retries a task, chat or job planning request, the retry keeps its place in line.
- A cancelled task leaves the line at once, and a request it had in flight stops.
The limit counts requests in flight. It does not limit tokens or requests per minute. A model’s performance test waits in line like any other request, so on a busy provider it can report the model as unreachable, and its time to first token includes the wait.
Azure settings
For theazure type, two extra fields appear:
Azure API Management (APIM) gateways are supported as the endpoint: set the Base URL to your APIM gateway URL to route model traffic through it for centralized policy, rate limiting, and logging.
Correlation headers
When theenableLlmCorrelationHeaders feature toggle is on, each LLM request the engine sends for ticket, job and task work carries the IDs of that work, so an LLM proxy in front of your provider, such as one that feeds Langfuse, can group the requests:
A request carries only the headers for the work it has: a standalone task sends no ticket or job header, and an AI Assistant chat sends none. Each value is the ID the Command Center shows in its page address, for example
/jobs/<job id>. Tenant and organization IDs are never sent. Every provider type receives the headers.
Deletion rule
A provider that still has models cannot be deleted. Remove or reassign its models first, or simply disable the provider instead.
Configuration
Create and edit providers in Command Center > Settings > Providers. A new installation starts with the one provider itsvalues.yaml names; add the others here. Adding or editing a provider does not require an engine restart.